Audit your Agent files
August 27, 2026
TL;DR: Your coding agent’s configuration has a half-life. Models improve, harnesses add capabilities, codebases change, and the instructions we wrote for an older version stay behind. Recent research finds inconsistent value from personalized skills. I now run Claude’s /doctor every few weeks, review memory separately, and ask each instruction to earn its place again.
I feel like there’s been a lot of confusion about skill files and what to do with your CLAUDE.md and AGENTS.md files, especially as I’ve been reading developer discourse on Twitter over the last few months. People have been saying things like, hey, keeping your skills and CLAUDE.md/AGENTS.md files up to date is a big pain point. Very often, people are trying to get them to steer their agents, but are having a hard time keeping them under 200 lines long, even if that’s an official target. People are finding it hard to keep them lean. They’re raising token costs. They can make the agent worse as you keep adding and adding and adding stuff to them.
And the official guidance that I’ve read is that you should be periodically deleting your CLAUDE.md, your skills and your hooks, like every couple of months, rebuilding only what matters. But my own experience with that is that people have this fear of, hey, I don’t know if that’s going to actually make things significantly worse. I’m worried that if I do, that quality is going to drop very heavily. And I don’t have an easy way to just quickly restore things or try this out. There’s so many different configurations I can use models with. And so it can feel like this advice comes across as easy to try out when it’s not always going to be that way. And sometimes all of these markdown files and practices can become outdated and they can hurt more than they help. But I do think that there is something in this advice about how models and harnesses do actually get much better.
I’m a fan of skills. The critiques are still fair.
I’m personally a big fan of Agent Skills. I and a few of my friends maintain some Agent Skill packages that have gotten a little bit of traction. I maintain Agent Skills, which is an SDLC-focused pack. My friend Paul Bakaus maintains Impeccable, which is a design-focused pack. And sentiment has been generally pretty positive with developers using skills with coding agents. They’re seen as a good abstraction for turning a generalist into a specialist, right? And they work pretty well with a lot of different coding agents and harnesses. So people like them.
One of the sets of critiques has been fair. Of course, you have many different people writing them for very different domains. There isn’t really a great playbook for how to do this. So we’re all really playing it by ear. And we try to learn from each other. We take on feedback from the community and we’re constantly iterating on these things. But skill hygiene continues to be very important. Sometimes you’ll find skill packs that have thin descriptions, or they’re a little bit on the vaguer side for their workflows. And so I still think that agent skills are something that I believe in, and I think that they have a lot of value. But as people have really leaned into them over the last couple of months, auditing skills has also become increasingly important.
You could be doing a bunch of different parallel projects or parallel tasks on any given day. For some of them, maybe you’ll try out new community skills, or maybe you’ll try putting together your own skills for them. And if you can imagine, over the course of a couple of months, those skills locally can build up, and you’re probably not going to use all of those. You’re probably actually going to use a fraction of them.
When I’ve gone and I’ve read Hacker News discussion threads on public skills, the debate is very much, you know, there are people who find value in skills. There are people who call them net negative. There are people who feel like there isn’t enough evidence presented about the value. There are folks who feel like they just add a lot of noise. There’s heavy token costs. They’re unreliable. I certainly think that there’s a lot of valid feedback in here. It is sometimes challenging to come up with enough evidence to show, for everyone’s workflows, that these are actually a net positive. But there are plenty of people who say they find these things beneficial, and then plenty of cases where the feedback is valid. Like, hey, show me that this is actually going to be useful enough for me to consider for my project.
Why agent configuration rots
People keep adding rules to their CLAUDE.md files and their skills every time that they see their agent steering them in the wrong direction. I’ve certainly done that over time. And then the file balloons, adherence drops, you add more and more rules and quality can end up getting worse. And you almost end up treating it as this full knowledge base instead of a short decision guide. And that’s a very classic mistake.
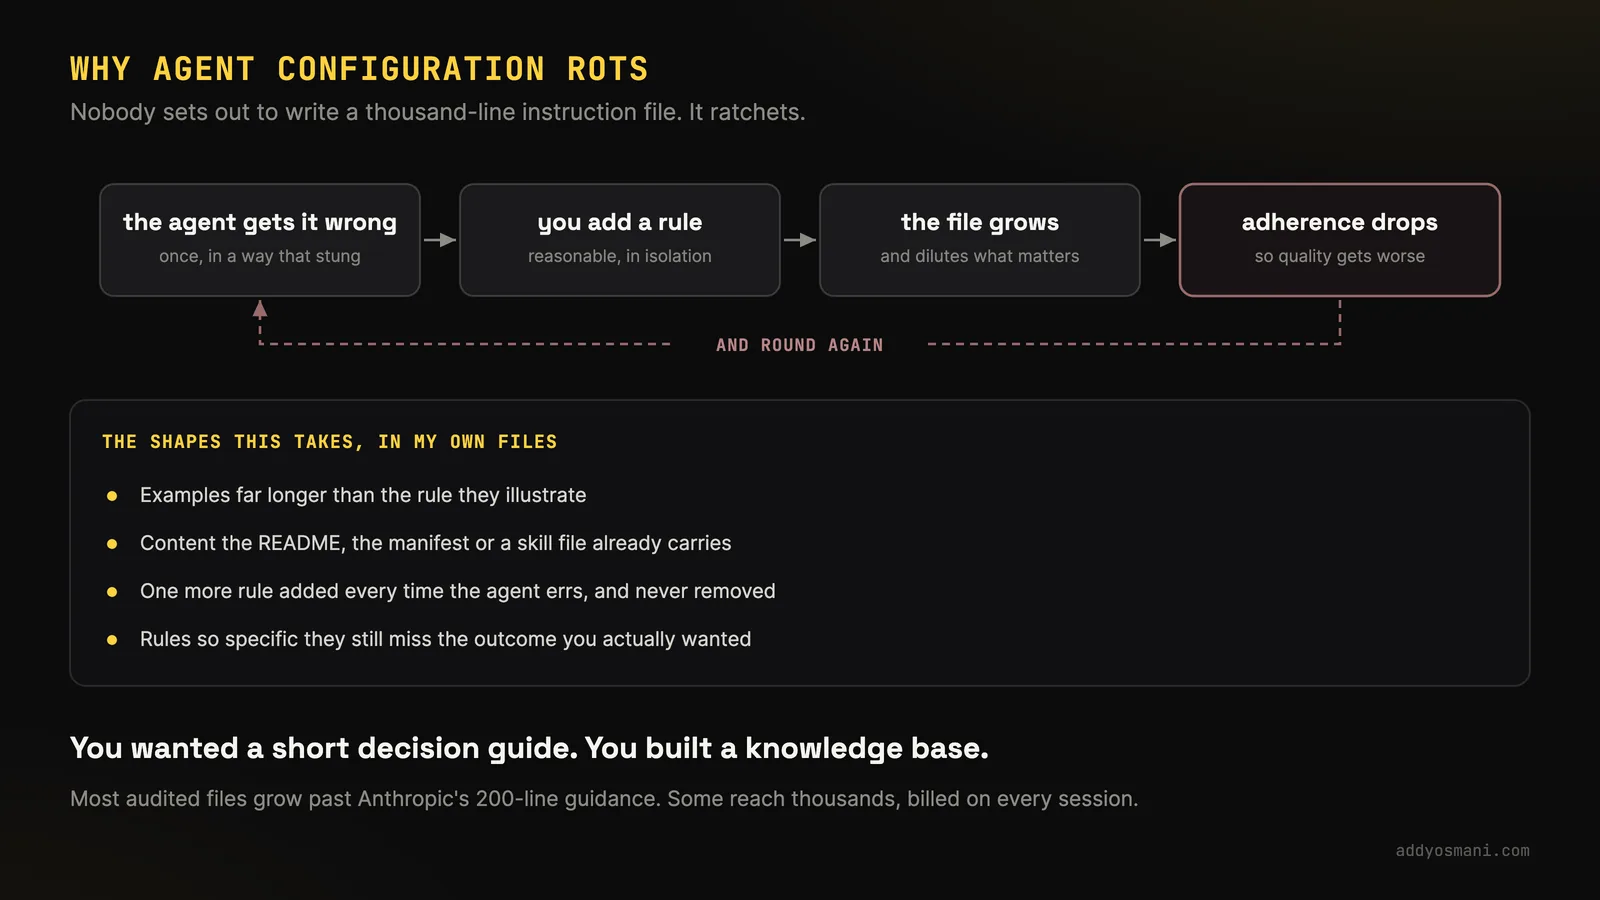
AGENTS.md and CLAUDE.md bloat is also another big problem. I think it’s pretty widely acknowledged at this point. There have been a number of different research exercises done on real repos, and they found that there were a lot of configuration smells that were pretty common. Context bloat is pretty common, skill leakage, lint leakage. And most of the agent files that these research exercises have tried out had at least one issue. Files generally do grow past the Anthropic guidance of 200 lines. Some even reach hundreds or thousands of lines, wasting tokens on every session.
And I’m to blame as well for this. When I try looking at some of the CLAUDE.md files that I’ve put together in the past, not for sharing with people but just in my own setup, I’ve also gone past 200 lines. And I found that there were a few common failure modes that I’ve seen in my own files. Things like overly long examples. Redundant content that may have been present in readmes or package manifests or skill files. Add a rule every time the agent errors. That kind of growth can keep compounding. And so I think that you kind of have to think about it in a very, very focused way. And I’ve also seen that being over-specific in your CLAUDE.md file, in AGENTS.md, can sometimes not actually lead to the outcomes that you want.
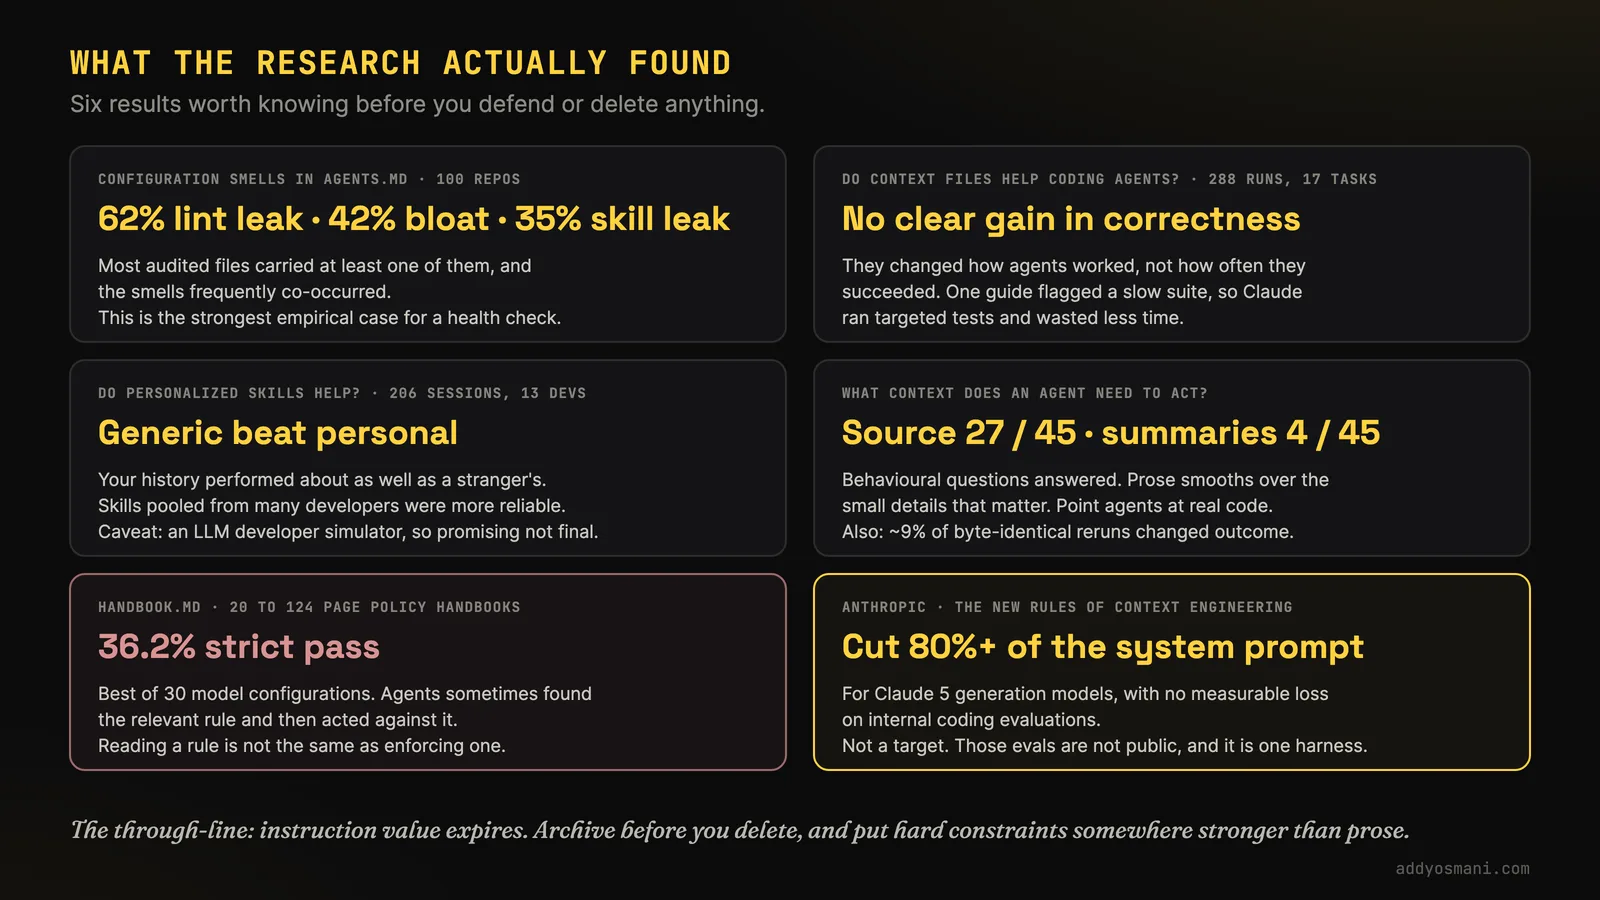
For the numbers: a June study of 100 popular repositories found lint-related leakage in 62%, context bloat in 42%, and skill leakage in 35%. And in The new rules of context engineering, Anthropic says it removed more than 80% of Claude Code’s system prompt for its Claude 5 generation models with no measurable loss on internal coding evaluations. That result is not a target; the evaluations are not public, and it covers specific models in a specific harness. The lesson is that instruction value can expire, so archive first, and if a rule must always hold, encode it in a test, hook, or permission rather than leaving it as prose the model might lose.
I think there’s been some really good research I’ve been reading over the last couple of months, some good empirical studies that will maybe help with the discourse. And I wanted to make sure that I was covering some of this in an article for people, as I think some people haven’t had time to read some of these papers as well.
Do personalized skills help coding agents?
I’ve been wondering how useful it would be for Claude Code or Codex to gradually learn how I like to work. Maybe I prefer small changes, want tests run a certain way, or don’t want the agent refactoring unrelated code. This paper tries to turn that interaction history into a reusable personal skill. The surprising result was that personalization didn’t help very much. A skill based on one developer’s history performed about as well as a skill borrowed from somebody else. A generic skill built from lots of developers was more useful overall.
For many of us, we think that having a bunch of skills for our specific workflow can actually make a huge difference. But some of the research actually says that that’s not necessarily the case, and that having skills based on broader engineering, broader community best practices, can actually make more sense and actually lead to more value. And, I’m sorry, I should also say, where they can add value is if you have skills that include more examples for specific tasks. And sometimes those broader community skills will have this. For example, if I’m trying to tackle a problem related to, let’s say, scheduling, and there’s a bunch of different ways to approach scheduling, a bunch of quirks around it. If my skills, whatever ones I have, have a bunch of very concrete examples and specificity around it, maybe those can help guide the agent in a certain way. Otherwise, just having some details about, oh, I’d prefer the formatting of my scheduling primitives to look this way, that’s not actually all that helpful.
Personalization did look more promising when the same preference recurred across several similar tasks, though the experiments used an LLM-based developer simulator, so treat this as promising rather than final. My takeaway is to begin with a strong generic skill and add personal rules gradually. I wouldn’t promote a preference into permanent agent memory because I mentioned it once.
Skills once again, when I talk to companies and I’ve talked to enterprises, they see it as high value. They think that individual engineer skills are useful, but then when you have a set of skills for a team or an org, they think that that can lead to compounding value, which is kind of cool. So you’ve got your engineering culture captured in there, your compliance rules, your brand, your internal tooling quirks, how you want to approach consistency across people and different coding agents, how you want to approach the review process and provisioning and any of those types of things.
Do context files help coding agents?
I’ve been using files like AGENTS.md and CLAUDE.md as a kind of operating manual for coding agents. This paper asks whether those files actually help Claude Code and Codex solve more tasks. Across 288 runs on 17 real tasks, they didn’t make a clear difference to correctness.
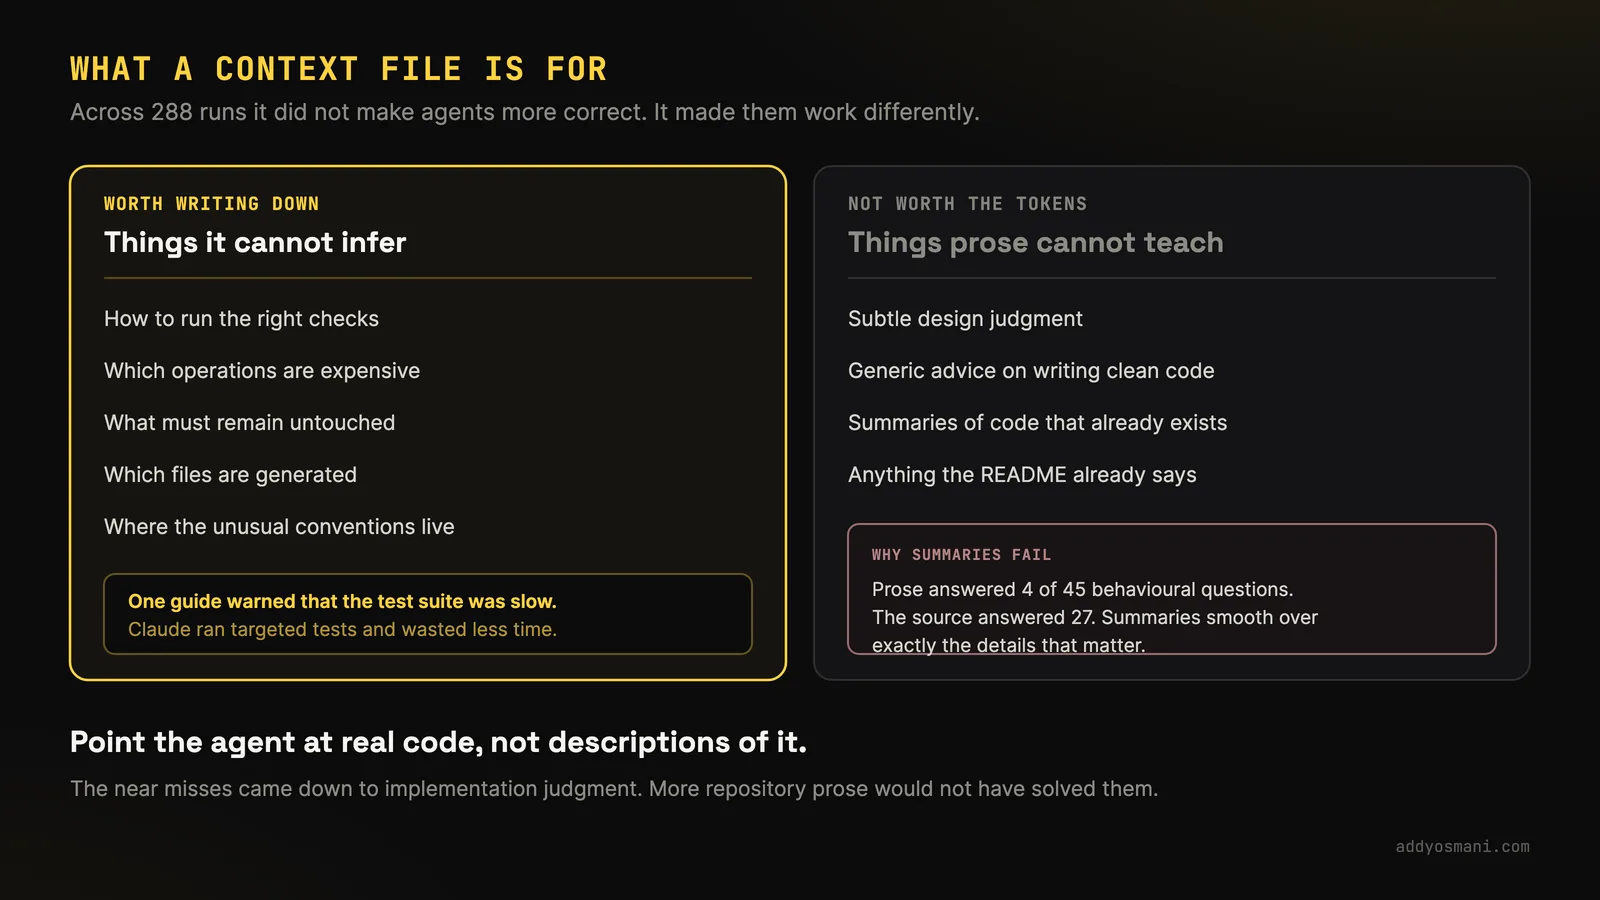
Context files did change how the agents worked, though. In one repository, the guide warned that the full test suite was very slow. Claude responded by running more targeted tests and wasting less time. It didn’t become better at implementing the feature, but it followed the repository’s workflow more efficiently. I think that’s the useful distinction. A context file can tell an agent about expensive commands, generated files, architectural boundaries, or project-specific safety rules. It can’t necessarily teach the agent how to make a subtle design decision; the near misses usually came down to implementation judgment, and more repository prose wouldn’t have solved those problems.
My takeaway is to keep repository context files focused on things the model can’t easily infer from the code: how to run the right checks, which operations are expensive, what must remain untouched, and where the unusual project conventions live. I wouldn’t fill them with generic advice about writing clean code. A related study points the same way: prose summaries answered 4 of 45 behavioral questions about code while the source itself answered 27 of 45, because summaries smooth over the small details that matter. Point the agent at real code, not descriptions of it.
What I found when I audited my own setup
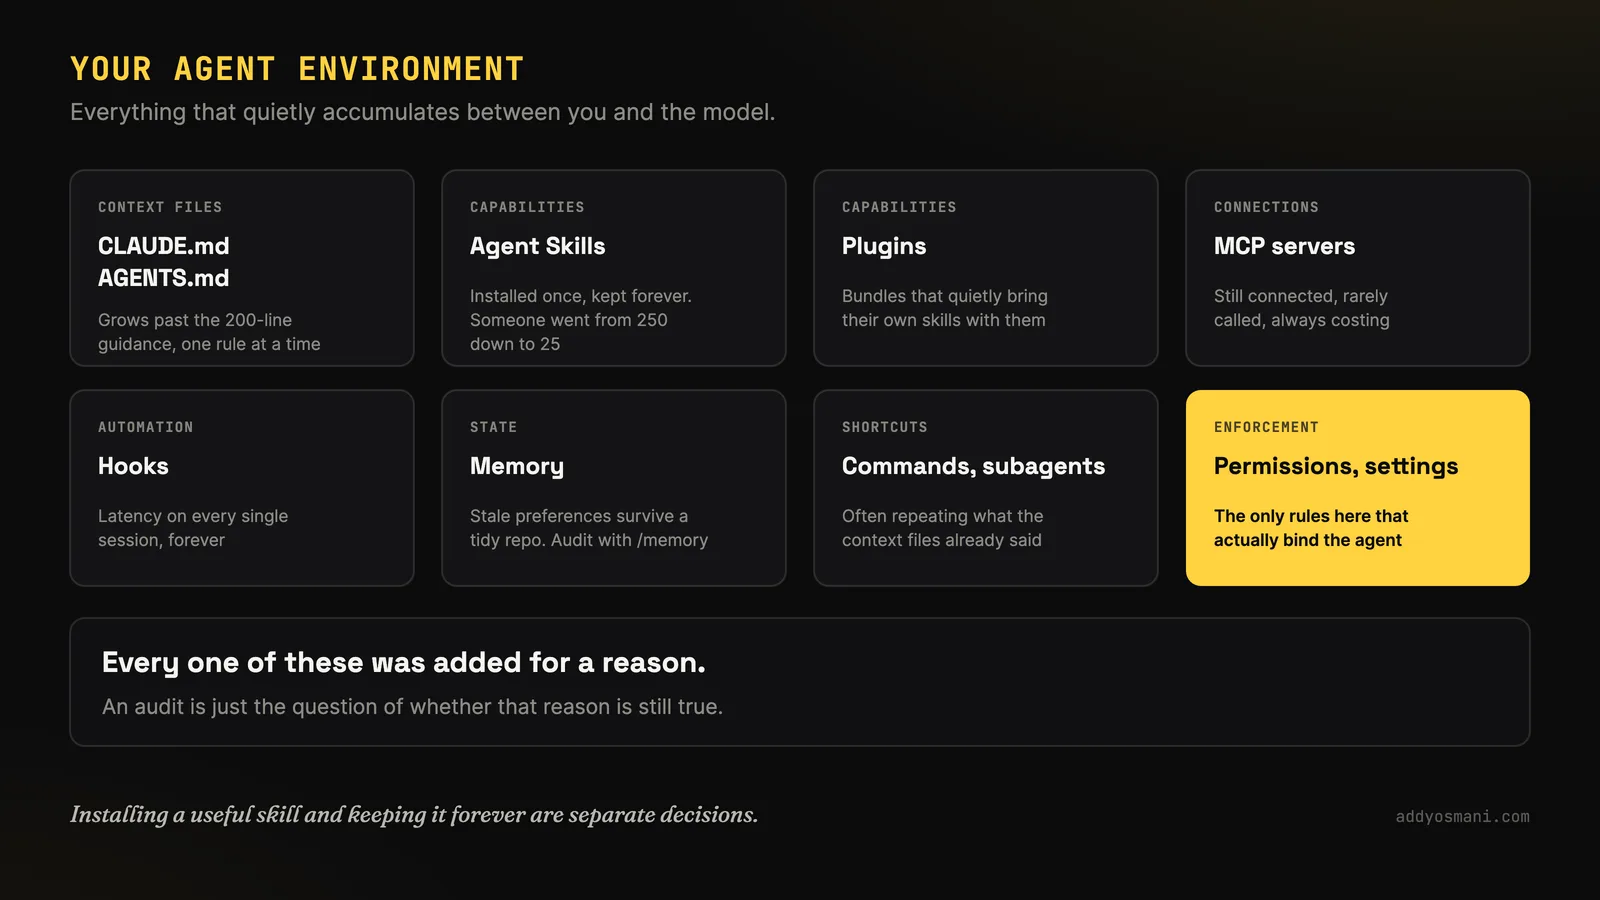
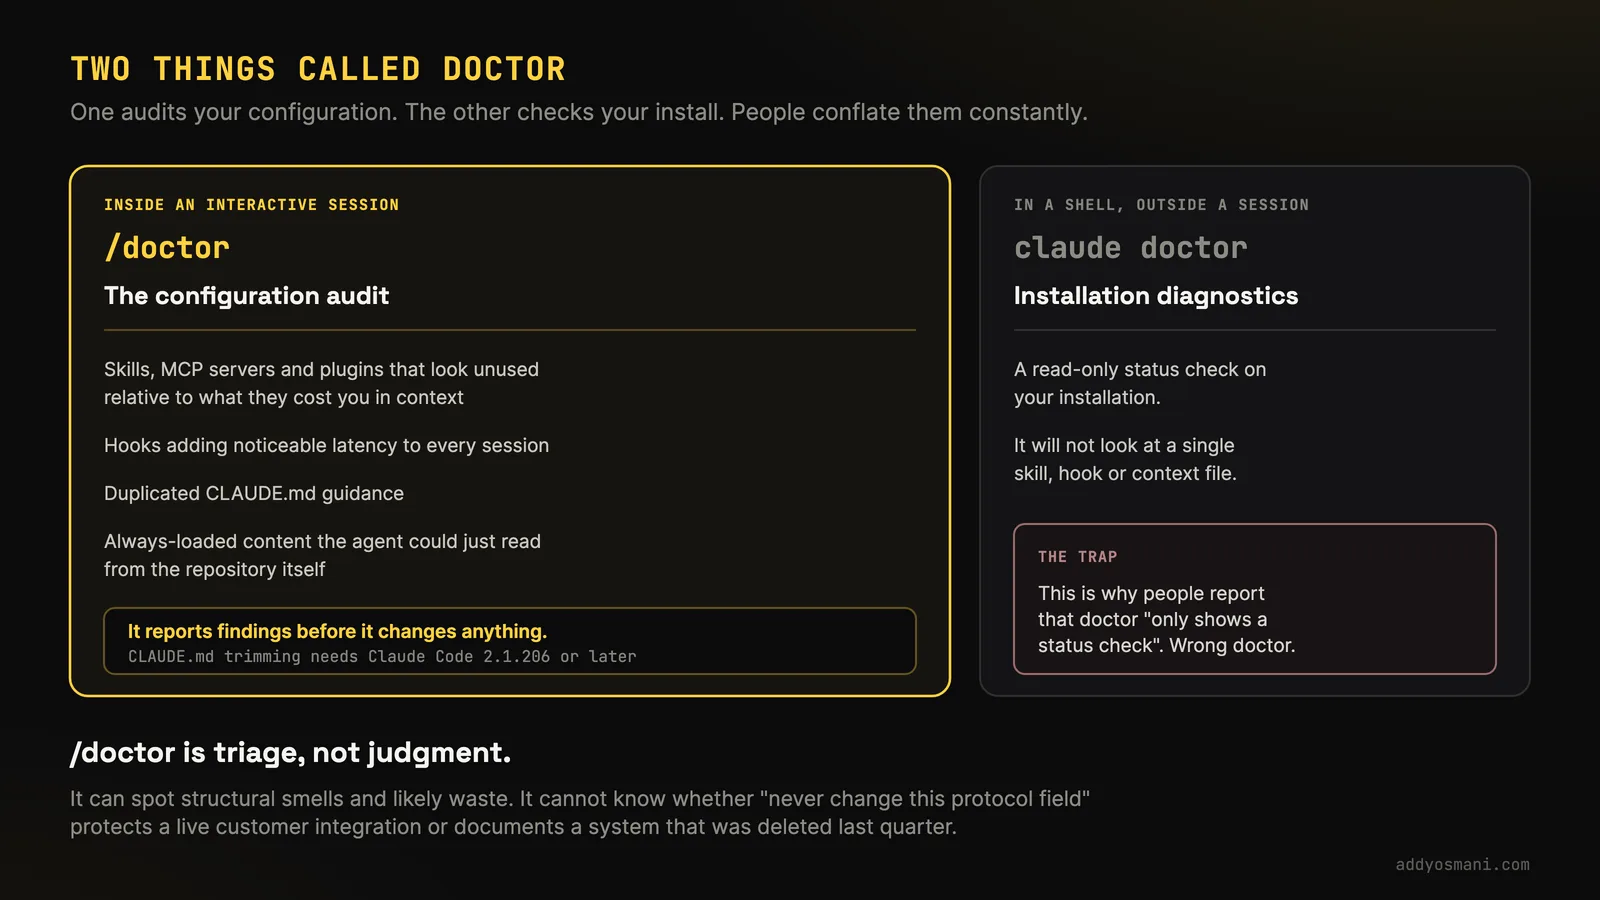
I was really happy to see Claude put out the doctor command in Claude Code. It’s a good hygiene command, and it basically runs a checkup covering unused skills and MCP servers and plugins relative to their context cost, whether you’ve got an over-specified CLAUDE.md file, slow hooks, or cruft, or things like that. And when I’ve run doctor on my own setup, I’ve been just shocked at things that were still hanging around that I’d completely forgotten about. Like, if you’d asked me, I wouldn’t have guessed that they were still there. I’d completely forgotten that I’d even experimented with them.
I’ll give you one example. At a point in time, maybe four or five months ago, I was curious about different writing skills that people were checking out. There were a lot of different anti-slop skills that people were experimenting with. And so I had tried out a bunch of different ones of those. And I was shocked because I’d completely forgotten how many of those I’d had installed. I had no idea. Like, are these things being triggered together? Or is one taking priority over another? Are they all being ignored? I’d just not realized that those things were still hanging around at all. And so auditing that was very useful. There were some design skills that some friends had written that I was trying out that I’d forgotten about. And now, as we’ve seen the community in some cases converge on some high-quality skills, I would prefer to lean on those than some of the other experimental ones that I tried from a few months ago.
I remember recently seeing a tweet where somebody was saying, yeah, I started auditing my skills and I went down from 250 to 25. And I was just like, how do you end up with 250 skills? That’s crazy. But experimenting with a lot of community skills, these can easily compound over time. And you don’t want to confuse your agent, right? So you’ve got to periodically lint and clean up your agent environment.
Installing a useful skill and keeping it forever are separate decisions.
Auditing quality, not just quantity
I think another thing about skills is just making sure that they’re high quality. Anthropic’s own Skill Creator now includes evals and a benchmark mode for trying to check on quality. There are good community tools for checking on SKILL.md quality. Like, do they have good descriptions, good triggers, clear steps and examples? There are more security-focused auditors and best practices for skills as well.
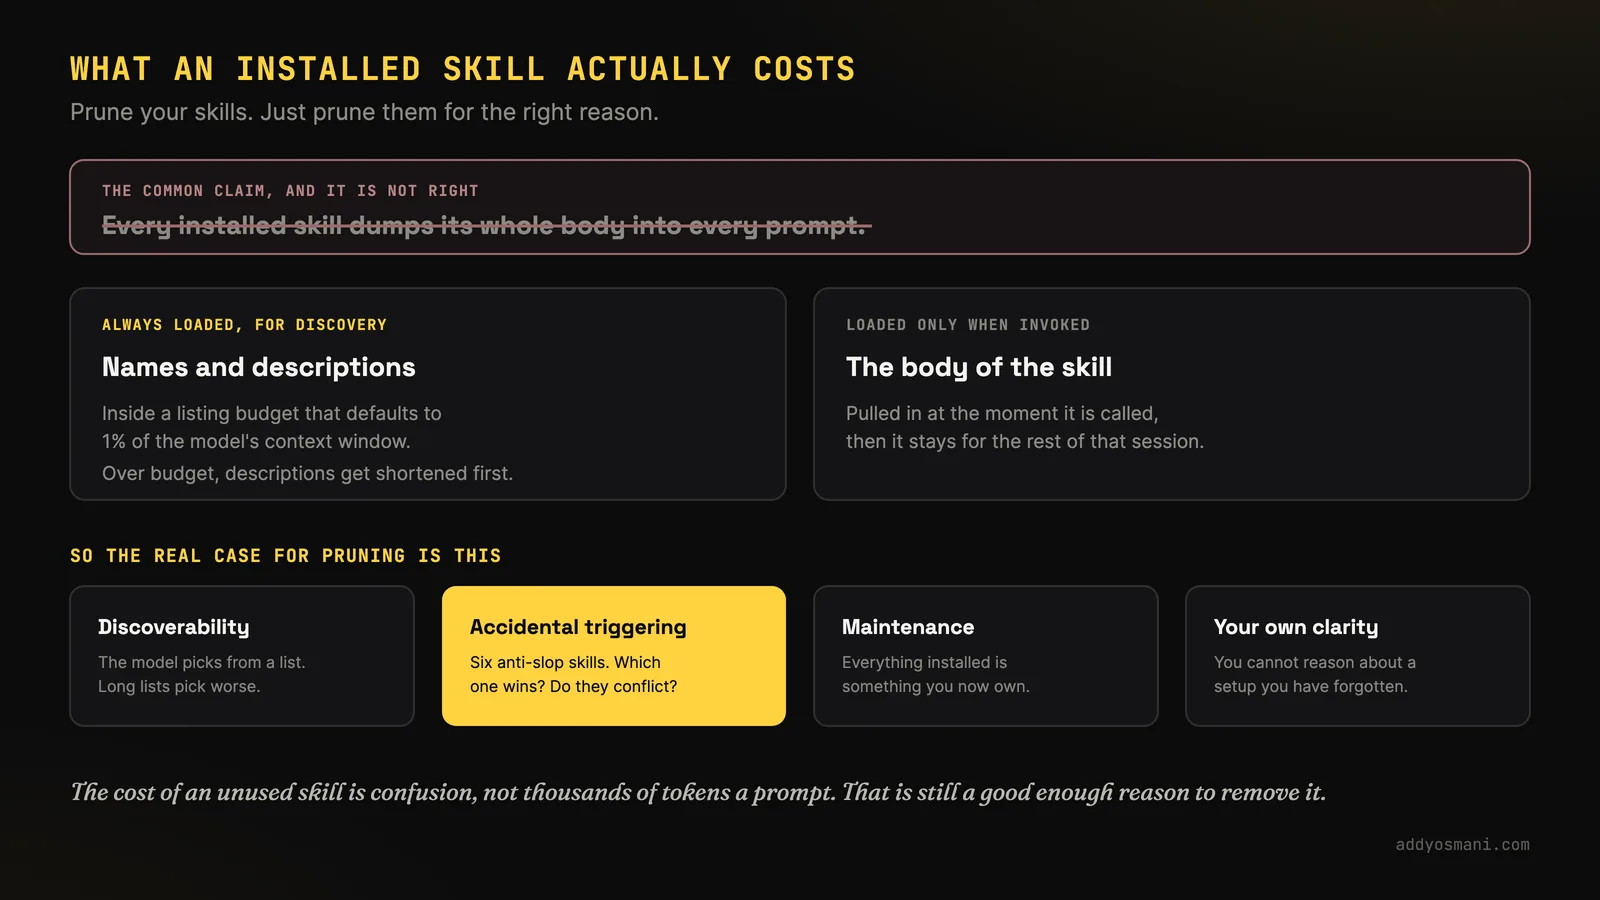
One naming trap worth knowing: in Claude Code, /doctor inside a session is the configuration audit, while claude doctor in a shell only prints installation diagnostics, which is why some people report that doctor “only shows a status check.” And an installed skill does not dump its whole body into every prompt: names and descriptions load for discovery within a listing budget defaulting to 1% of the context window, and the body loads on invocation. I also review memory separately with /memory, since auto-memory can hold stale preferences even after the project files are tidy.
Audit on a cadence, then test removal
And so I think there’s high value personally in, like maybe every couple of weeks, maybe at once a month even, just running doctor on your skills, on your setup, and auditing what you’re doing and seeing, okay, well, what still holds true? And then if you have the time, actually going and seeing, like, if you were to delete your skills, or you were to instruct your agent, well, don’t use any local skills at all. Only try to complete this task using the raw model and harness. And see, is it actually okay without using any of these skills? And then you can ask yourself, okay, well, actually, maybe it’s okay for me to delete these skills. Maybe that’s fine.
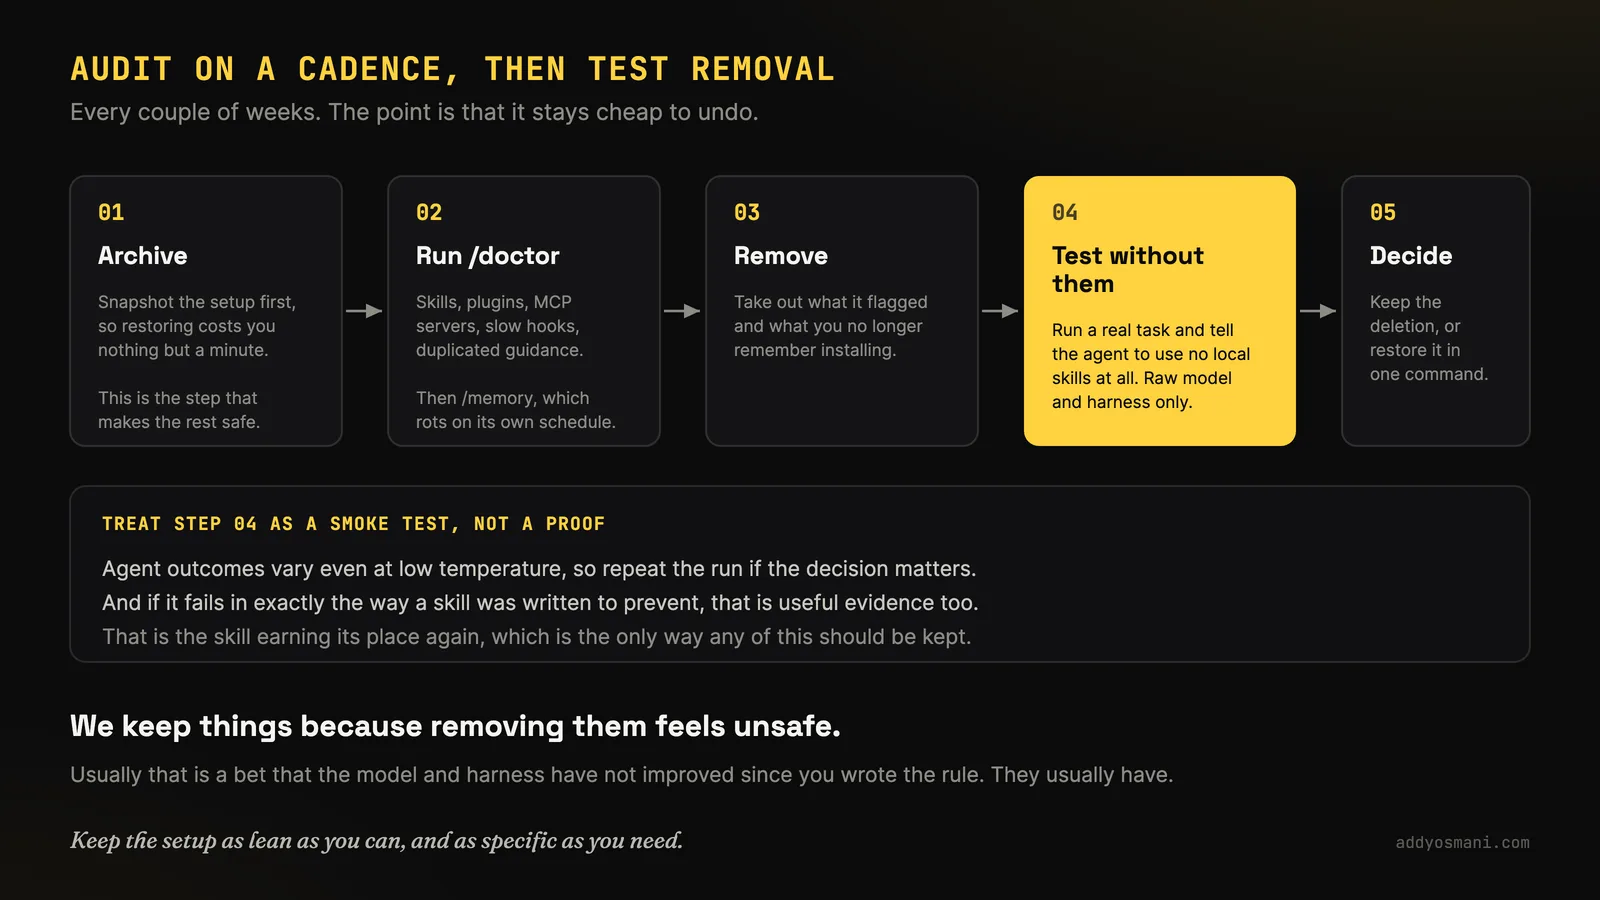
But I feel like sometimes we lean on skills and all of these things we’ve installed as a crutch, because we feel like it’s unsafe to remove them, because we don’t trust that the model and harness have actually gotten better. So I think that there’s a lot that we can experiment with and learn.
Continue to have hygiene around them. Audit the quality, the security. Do run doctor commands regularly, and try to just make sure that you’re keeping your local setup as lean, but as specific, as is needed.